


Attribute extraction and normalization
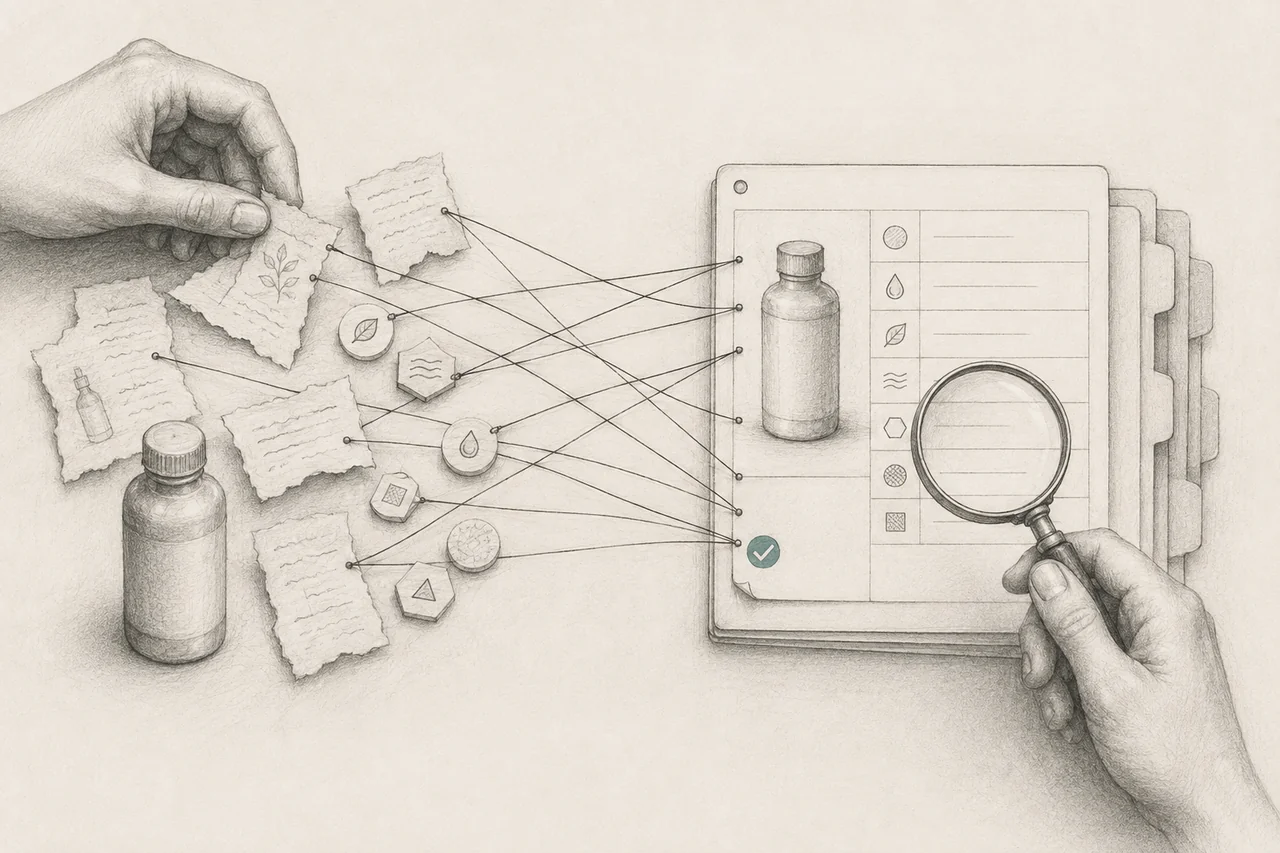
Extract values from approved sources and normalize terminology, units and formats. Preserve the original value for review.
Product Data Enrichment
Build controlled AI-assisted workflows that extract, normalize and enrich product information while keeping merchant rules and human review in the loop.
Built around your stack
Possible connections, scoped to your systems and permissions.
Supplier documents, feeds and spreadsheets often describe the same attributes differently. Missing fields weaken product discovery and comparison; inconsistent content creates additional review work. A controlled enrichment workflow can prepare structured catalogue information while retaining the source evidence needed to check it.
See the workflow
Select a step to see how the context, output and controls connect.
Supplier documents and feeds provide source material. Retain a reference to the record behind each proposed value.
Extract and normalize supported attributes using a defined field structure. Leave unsupported values unresolved.
Operators can resolve uncertainty and release approved information into the catalogue or PDP workflow.
Extract values from approved sources and normalize terminology, units and formats. Preserve the original value for review.
Identify gaps, assemble structured specifications and flag values that cannot be supported by source data.
Prepare consistent product content from verified attributes, with merchant standards and review before use.
Suggest a category or product type against an agreed taxonomy, with exceptions sent to an operator.
Check whether descriptions, attributes and feature summaries contradict one another or omit required information.
Where appropriate, prepare structured content for language review while preserving units, terminology and product meaning.
Capture the supplier record, product document or approved feed.
Extract, normalize or draft with a defined output structure.
Check formats, allowed values, required fields and source support.
Resolve uncertain values and conflicting sources with a responsible operator.
Release the reviewed record to the agreed catalogue or content workflow.
Unknown attributes should remain unknown until there is evidence to resolve them. A model should not invent dimensions, certifications, compatibility or other product claims. Store source references and transformation status with the proposed data; use deterministic checks for formats and allowed values. Define which changes need human review, and retain an audit trail of corrections.
The architecture can connect to product feeds, PIM, ERP, commerce APIs and Shopify. Define field ownership and the approved destination before synchronization. An enrichment step can feed a PDP workflow, improve discovery inputs or create a queue for product specialists without granting the AI direct publishing permissions.
Start with common records, difficult exceptions and examples of known correct output. Measure field coverage, extraction accuracy, reviewer corrections and processing effort. The first release can focus on one data source or attribute family, with expansion based on validated quality and operating cost. Lumethica can scope the workflow, interface and integrations before a full catalogue rollout.
Related
FAQ
Only where the available source data supports a value. Unsupported or conflicting information should be flagged for review rather than presented as a fact.
Yes. The integration scope can include approved feeds, files and product systems. A sample audit identifies formats, field mappings and data quality constraints.
Use structured validation, source trace and representative evaluation records, with human review for uncertain or higher-impact changes.
Yes. Approved records can enter a controlled product-content workflow, with validation and publishing permissions preserved.
Define the first useful release
Start with your catalogue, current process and the outcome you want to improve.